Job aggregators look the same everywhere: a search box, a list of jobs, an apply button. But under the surface, no two countries work the same way. A job aggregator that serves ten countries is really running ten different data pipelines and ten different rulebooks inside one product. This article explains how aggregators adapt to regional markets: where the listings come from, how locations are normalized, how search works across languages, and how compliance changes from country to country.
One product, many markets
In a single country, a job aggregator is a plumbing problem: connect feeds, clean the data, index it, search it. Going global turns it into a coordination problem. Every country has its own dominant job boards, applicant tracking systems, languages, data rules, and even ways of writing a job title.
The mistake many teams make is treating a new country as "the same system, translated." The systems that survive treat each country as a separate data universe sharing one platform underneath. The search box is the same; almost everything behind it is localized.
Where listings come from in each market
The first regional difference is the source mix. Listings arrive from three places: structured feeds (ATS and HR software integrations, XML feeds from job boards), direct employer postings, and crawled career pages. But the weight of each source changes dramatically by country. In mature markets, a few large applicant tracking systems dominate, so a handful of integrations covers a huge share of listings. In others, listings are scattered across dozens of local boards and thousands of employer career sites, so crawling does the heavy lifting. An aggregator launching in a new region starts with a source audit: which systems and boards actually carry the country's job volume?
Location is never as simple as it looks
Location is the single messiest field in job aggregation, and it gets worse across borders. Different boards describe "where the job is" in completely different formats: one uses a clean list of country names, another uses free text like "APAC, EMEA, LATAM," a third uses region names plus flags, and a fourth often leaves the field empty or just says "Remote."
So the aggregator normalizes every listing into one canonical shape — a country code, a region tag, a city, and a flag for remote, on-site, or hybrid. The "Remote" case is where candidates get confused: most "remote" listings are really "remote within one country" — the board says "Remote" but the ad says residents of one country only. Aggregators parse eligibility text into structured rules — allowed and excluded countries, required time zones — so a searcher in Germany does not waste applications on jobs they can never take.
Cross-border search also needs local geo intelligence: Indian job seekers search by city, European searches often filter by commuting distance, and Gulf markets filter heavily by visa eligibility. One search ranking cannot serve all of these.
Search has to speak the local language
Translating the interface is the easy part. The hard part is indexing job descriptions written in different languages. A "software developer" posting in São Paulo might say "desenvolvedor de software"; a German posting says "Softwareentwickler". If the index treats these as unrelated strings, international search falls apart.
The practical solution has two layers. First, the index uses language-specific analyzers — each language gets its own stemming and tokenization, because German compound words and English phrases do not break apart the same way. Second, the platform builds a shared taxonomy of roles and skills that maps localized titles to one canonical job family. That taxonomy is built market by market, and it is never finished.
The rules change at every border
Every region brings its own compliance rules. Europe's GDPR sets strict rules on storing personal data — including applicant data and search history. Other regions have their own data-residency expectations, consent rules, and retention limits. An aggregator operating globally cannot have one data policy; it needs a compliance matrix, with per-country retention periods, deletion workflows, and hosting choices.
This affects engineering directly. Every record needs a "jurisdiction" field from day one, so the system can apply the right retention rule to each record and prove it can delete data on request. Compliance becomes a data problem instead of a legal scramble later.
Ranking is local too
What makes a job "relevant" differs by region. Freshness matters more in fast-moving markets where listings go stale in days. Elsewhere, company reputation or salary transparency weighs more. Some regions rank official career-page listings above scraped copies of the same job; others prioritize verified employers.
Good aggregators therefore parameterize ranking: the ranking formula is shared, but the weights are tuned per market based on click-through and application data. The system learns each country's behavior separately instead of averaging the world into one model.
The architecture that holds it together
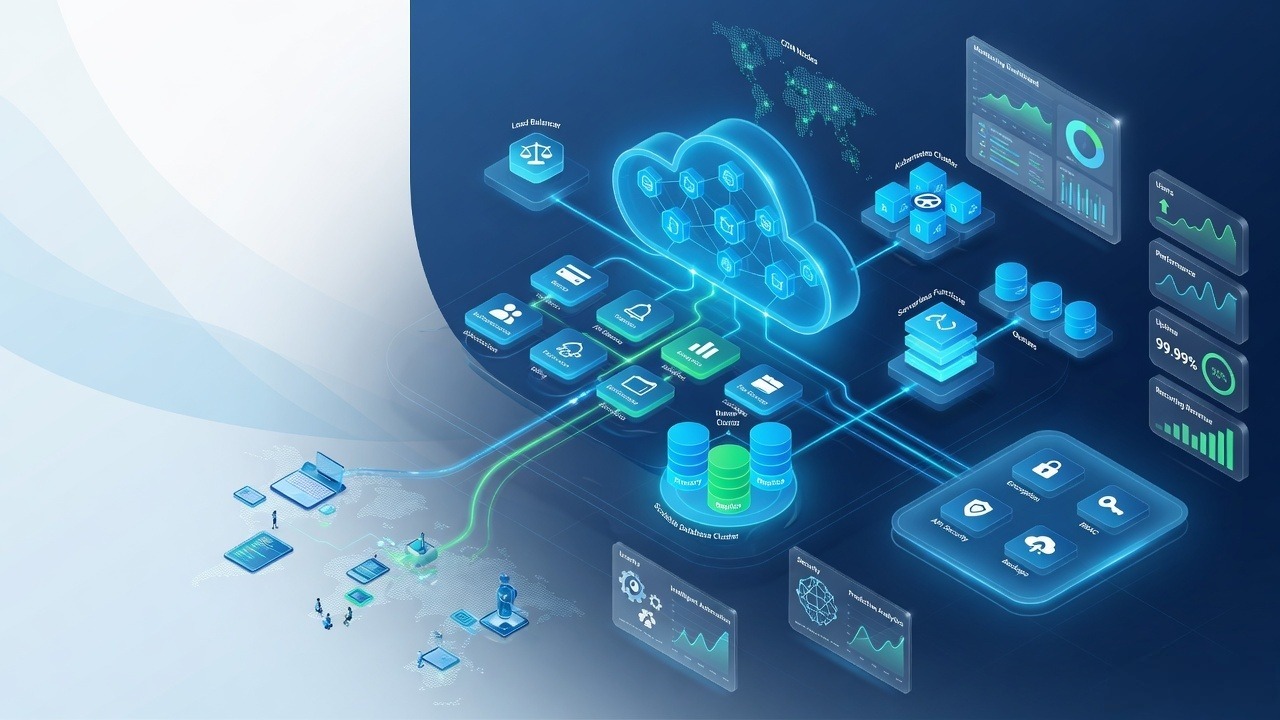
So what does the system actually look like? A multi-region job aggregator is typically built as one shared platform with per-country configuration:
- Per-region source connectors — integrations and crawlers configured for each market's actual boards and ATS systems.
- A normalization layer with regional rules — especially for location, currency, and job-type fields.
- Per-language indexes with language-specific analyzers, plus a shared cross-locale role taxonomy.
- Per-country ranking weights, learned from local user behavior.
- A compliance matrix — jurisdiction on every record, per-country retention and deletion.
- Regional data hosting where the law requires it.
The pattern is: shared platform, regional configuration. New countries launch faster because the engine exists — but each still gets its own source audit, its own taxonomy work, and its own ranking tuning. There is no "flip a switch" for a new market, only a well-practiced playbook.
Frequently asked questions
Do job aggregators work in every country?
No. Aggregators work country by country, because each market needs its own source connectors, its own language index, and its own compliance rules. The largest aggregators cover dozens of countries, but coverage is always uneven — strong in mature markets, thinner where listings are scattered across small local boards.
Why does "remote" sometimes mean "remote in my country only"?
Because boards and employers say "remote" loosely, but tax, payroll, and legal constraints restrict where the worker can live. Aggregators parse the eligibility text into structured rules (allowed and excluded countries, time zones) so searchers only see jobs they can actually apply for.
What makes a job aggregator truly localized?
Four things: the right local sources (not just global boards), language-aware search with a regional job-title taxonomy, per-market ranking tuned to local behavior, and per-country data compliance. Translation alone is not localization.
What is the hardest part of running a job aggregator across many countries?
Normalization — turning each market's inconsistent data (locations, titles, currencies, job types) into one clean schema. Crawling and indexing are solved problems; cleaning fifty different ways of saying "where is this job" is the ongoing work.
Talk to us about your platform
If you are planning a job aggregator, a regional job board, or any multi-country listing platform, we can help you design the source connectors, the normalization layer, and the localized search your market needs. Get in touch with InRay Labs — we build data-heavy SaaS platforms that work at scale.