Job Feed Management at Scale: Importing Millions of Listings Without Slowing Your Platform
Job feed management is the pipeline that imports listings from job providers on a schedule — and the engineering discipline that keeps those imports from ever touching your live site's performance. At scale, a single provider feed can run to hundreds of megabytes holding hundreds of thousands of jobs. Import it naively and you will exhaust memory, lock your database, and take the site down with it. Here is how to do it properly.
Why are feed imports dangerous?
Three things kill naive importers:
- Memory. Loading a 600 MB XML file into memory crashes the worker before the first job is saved.
- Time. Processing 190,000 jobs inside a web request will time out many times over.
- Locks. One giant database transaction inserting hundreds of thousands of rows blocks the reads your live search depends on.
Every one of these is a solved problem — but only if the pipeline is designed for it.
Schedule pulls — never import on request
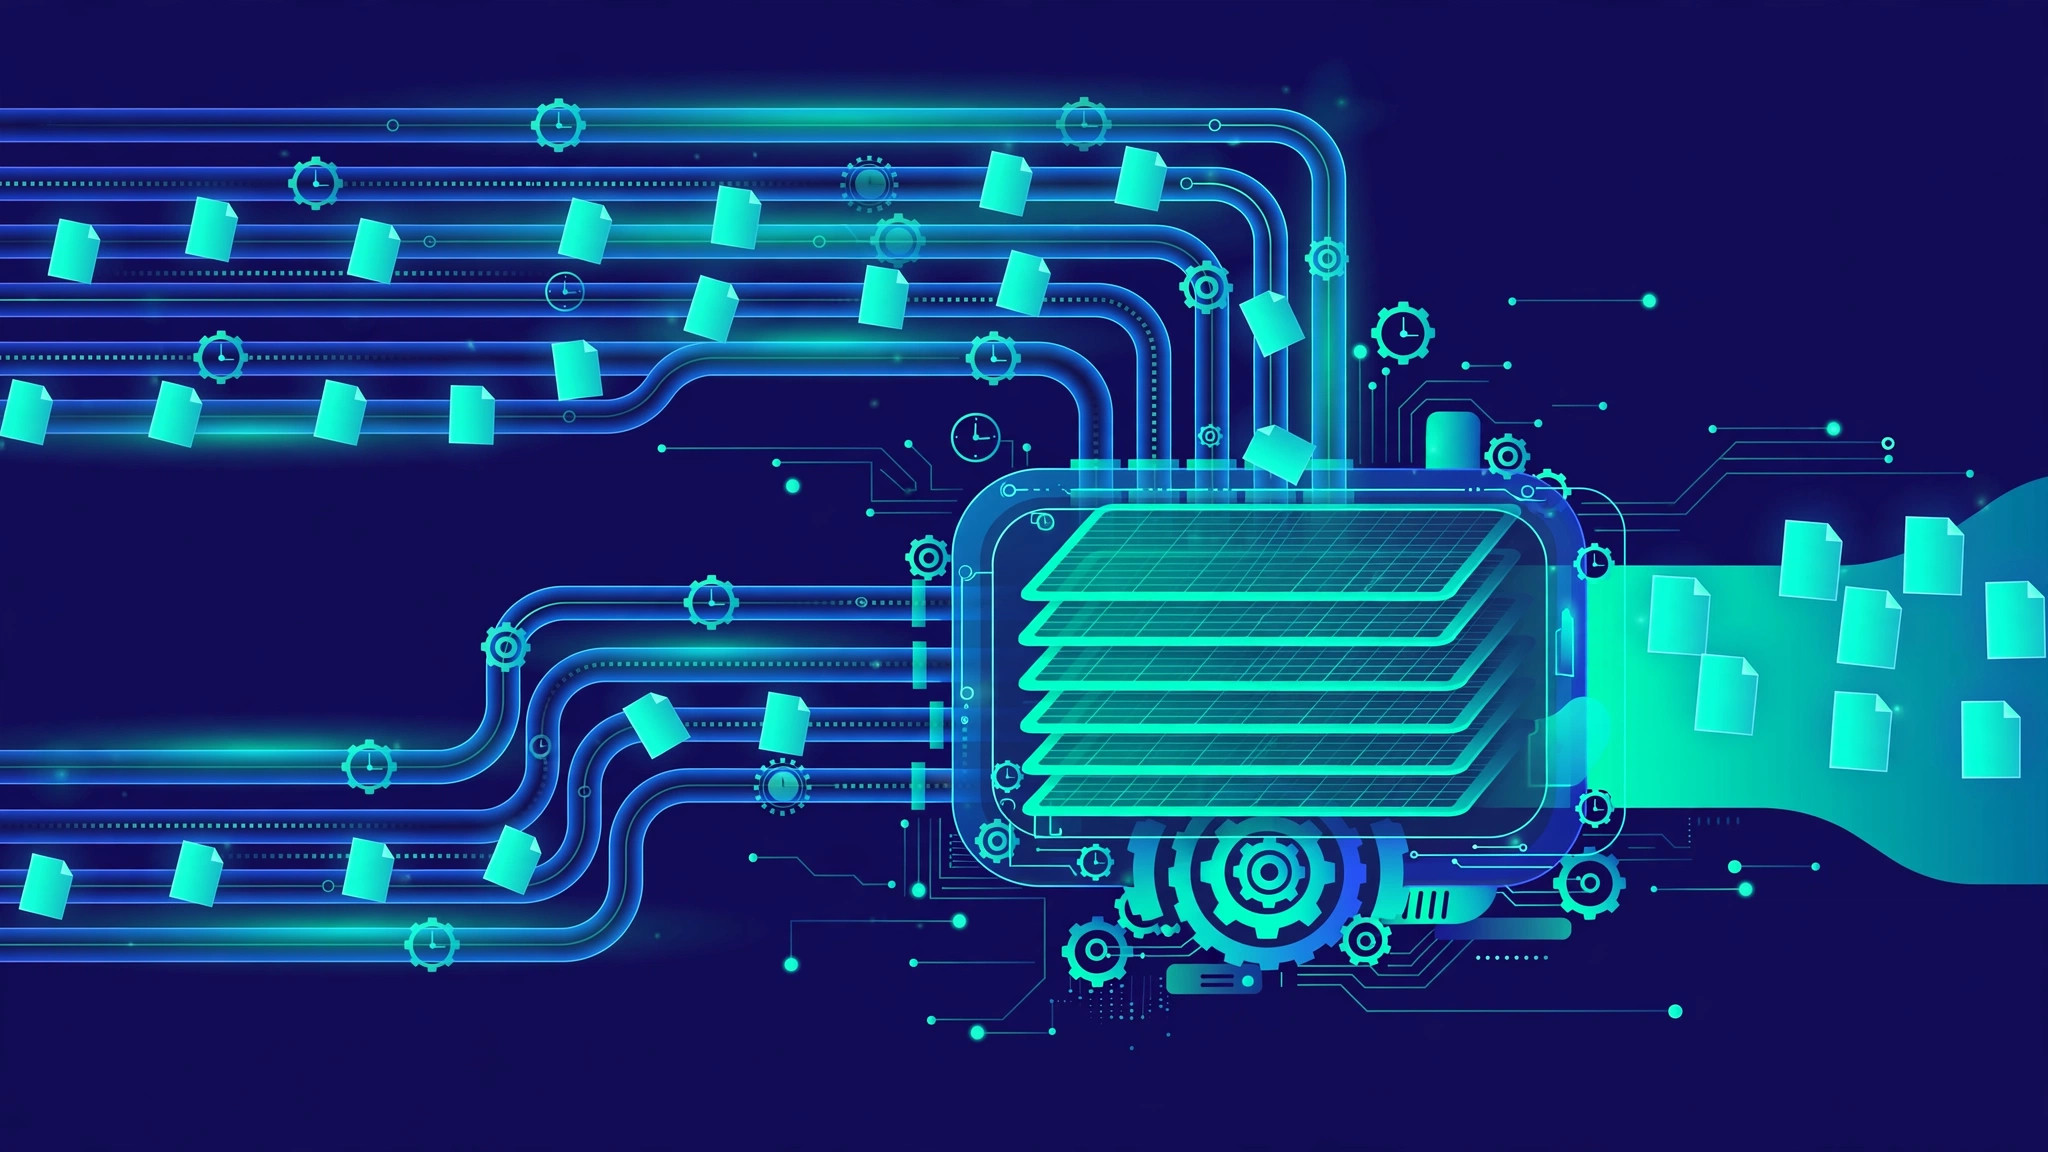
Each provider gets its own cadence: hourly for high-churn sources, daily for the rest, with jitter so providers don't get hammered on the hour. Imports run as background jobs on a scheduler and queue — never inside a web request, and never triggered by a user clicking a button.
Stream the parse — never load the whole feed
Parse the feed as a stream: read it job by job with an event-driven parser and write in batches of a few hundred rows. Memory usage stays flat whether the feed holds ten thousand jobs or ten million. The file size stops being a constraint.
Isolate ingestion from live traffic
This is the golden rule: a job seeker searching the site should never be able to tell an import is running. In practice that means separate worker processes and queues for import jobs, heavy imports scheduled off-peak, and batched, lock-friendly writes while live search keeps reading undisturbed. Ingestion and serving are different workloads — give them different lanes.
Normalize at the edge of the pipeline
Every provider's feed speaks its own dialect — different date formats, salary conventions, location fields, HTML encoding. Write one mapper per provider that converts its dialect into your canonical job schema before anything touches the database. A new provider means a new mapper, not a schema migration and not a special case in your core code.
Deduplicate deterministically
Use the provider's stable job ID as the primary key wherever it exists, and fall back to a fingerprint of normalized title, company, and location. Track first-seen timestamps per job so each run can classify listings as new, updated, or closed by set comparison — the same input always produces the same result, which makes the whole pipeline testable.
Fail safely — partial imports never go live
Two rules protect you:
- Stage, then promote. Import into staging tables, validate counts and schema, then promote to live. A corrupt feed should fail in staging, not on your homepage.
- Never close jobs on a failed run. A listing missing from a provider's feed is marked closed only after a complete, successful fetch. A timeout or partial parse must never trigger mass closures.
And monitor the schedule itself: alert when an expected import hasn't succeeded within its window. A missing successful run is the signal that matters — stack traces alone won't tell you an import silently stopped.
Frequently asked questions
What is a job feed?
A machine-readable listing of a provider's open jobs — usually XML or JSON — published so aggregators and job boards can import them in bulk on a schedule.
Should we use XML feeds or APIs?
Use whatever the provider offers. APIs are cleaner and support incremental pulls; XML feeds carry more volume but need streaming parsers and per-provider mappers. Most large aggregators support both.
How often should feeds update?
Match the churn: hourly for high-volume boards, daily for smaller providers. Freshness is a trust feature — stale listings cost you job seekers.
Need feed infrastructure that holds up?
We have built feed management systems that import millions of jobs on schedule without affecting platform performance — streaming parsers, isolated workers, deterministic dedup. If your job platform is outgrowing its importer, talk to our engineering team.