How Job Aggregators Work: From Millions of Listings to One Search Box
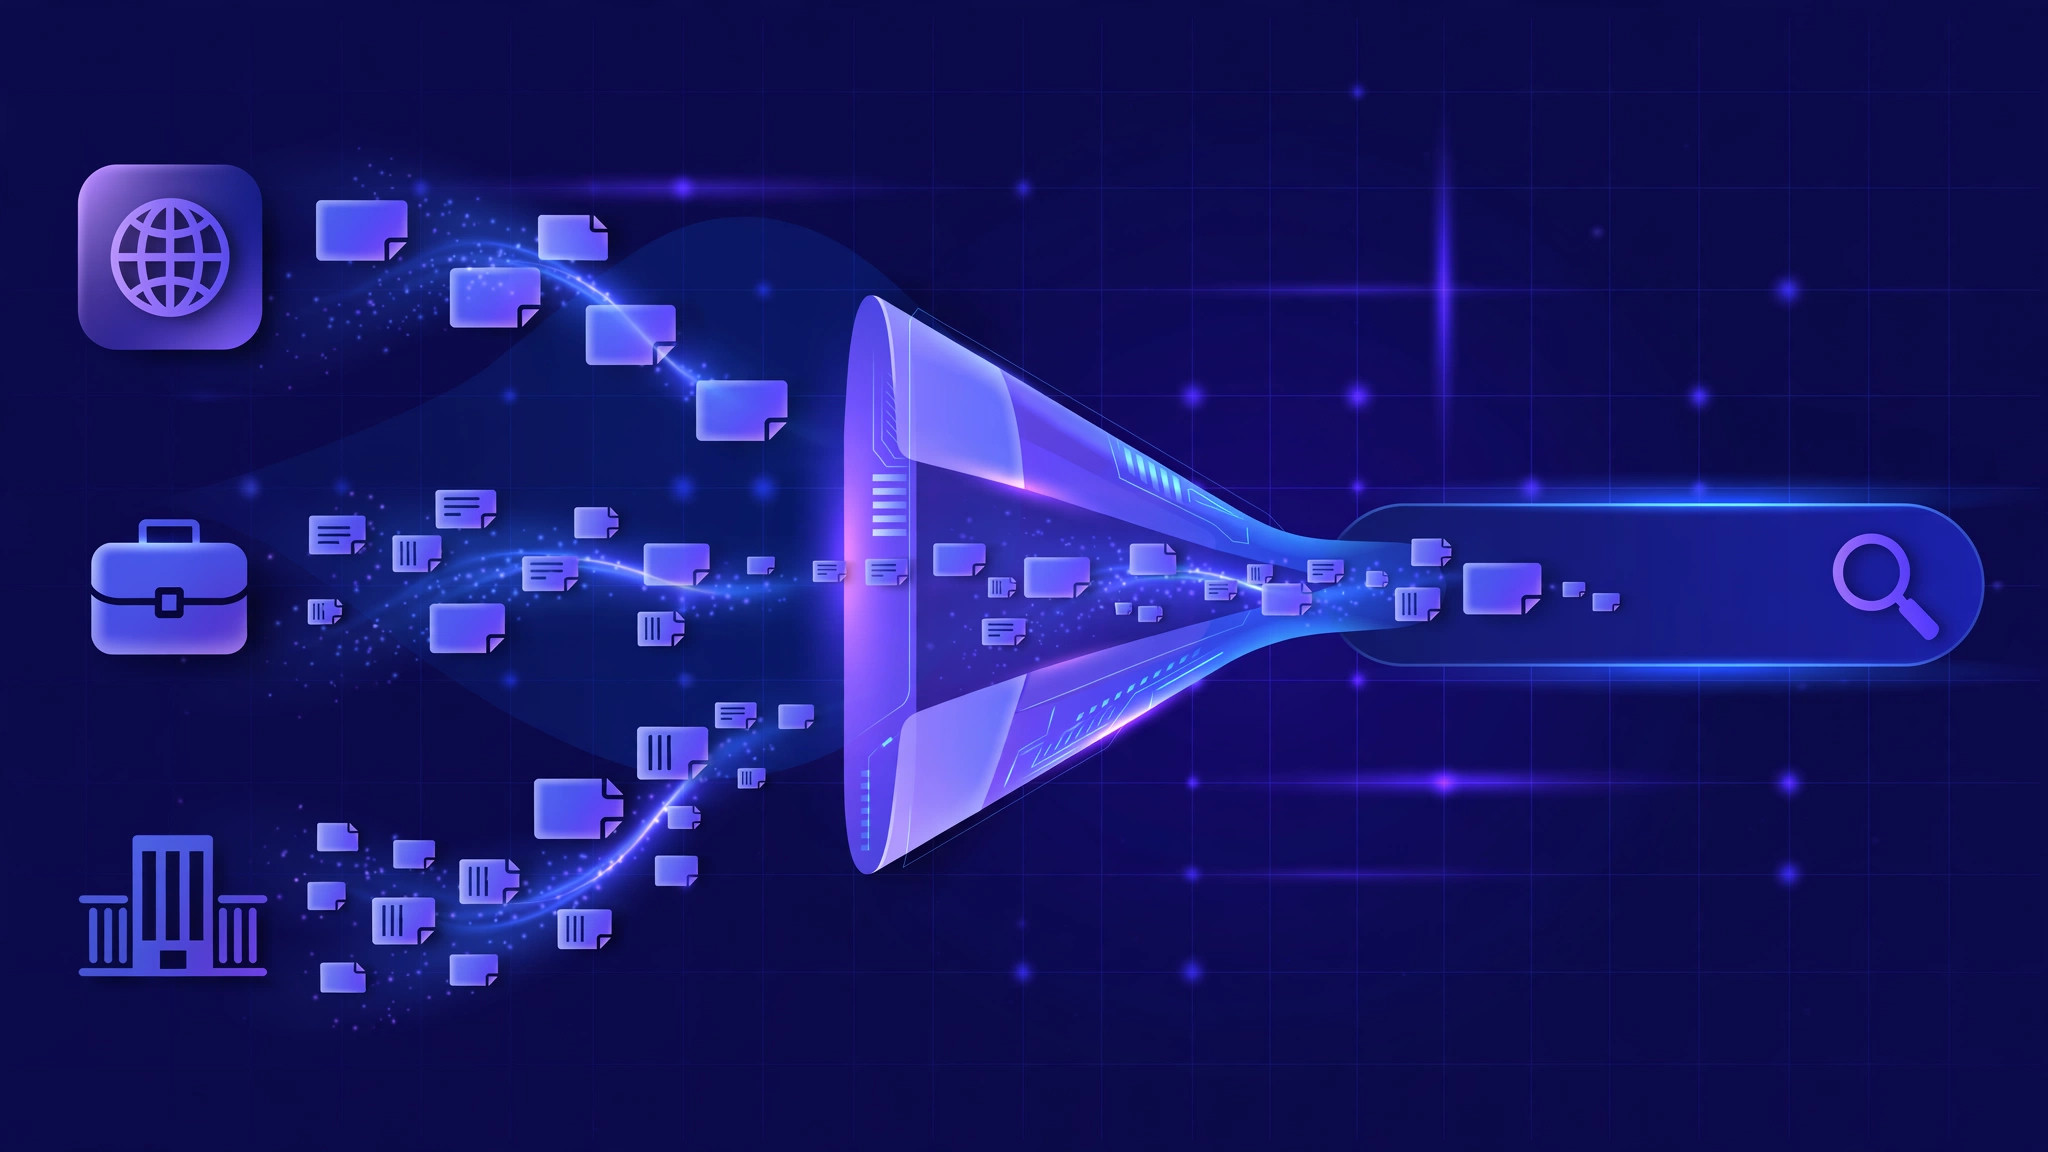
A job aggregator is a search engine for jobs. Behind a single search box sits a pipeline that pulls listings from thousands of sources — company career pages, applicant tracking systems, and bulk job feeds — converts every format into one clean schema, removes the duplicates, and keeps the whole index fresh. Here is how each stage of that pipeline works.
Where do the listings come from?
Aggregators rarely host original listings. They collect from four kinds of sources:
- ATS APIs. Applicant tracking systems like Greenhouse, Lever, Ashby, and Workday expose structured job feeds — often a single JSON endpoint per company. This is the cleanest source: titles, locations, departments, and sometimes structured salary data arrive in predictable fields.
- XML job feeds. The classic bulk channel. Providers push large XML files — hundreds of megabytes holding hundreds of thousands of jobs — on a schedule. High volume and messy formats, but unmatched coverage.
- Career page crawling. For employers with no feed, crawlers fetch career pages on a polite schedule and extract listings from the HTML.
- Direct employer posting. Many aggregators also let employers post directly, which guarantees clean data for those listings.
The strongest aggregators use all four. No single source covers the whole market.
How does ingestion work?
Every source gets its own schedule. Large job boards might be pulled hourly; a small company's ATS feed, once a day. Two rules matter:
- Pull incrementally. Track what you have already seen and fetch only what changed. Re-downloading millions of listings every cycle wastes everyone's bandwidth.
- Be polite. Rate-limit requests per domain, respect access rules, and back off when a source is slow. An aggregator that hammers career pages gets blocked — and a blocked source is a dead source.
How do thousands of formats become one listing?
This is normalization, and it is where most of the engineering lives. Every source speaks its own dialect:
- Dates arrive as "Posted 3 days ago", "2026-10-13 10:58:56 UTC", or a real ISO timestamp.
- Descriptions come double-encoded as HTML entities and need decoding before the tags are stripped.
- Locations say "2 Locations" instead of naming them; salaries hide inside description text like "$90k–$120k".
Each source gets a mapper that converts its dialect into one canonical job object: title, company, location, employment type, salary range, description text, apply URL, posted date, source name, and the source's own job ID. Adding a new provider means writing a new mapper — never changing the schema.
How are duplicates removed?
The same role usually appears in several places: the employer's career page, two job boards, and an ATS feed. Show it five times and the product looks broken; show it once and the job seeker trusts the result count.
Dedup works in two layers. First, fingerprinting: a hash of the normalized title, company, and location catches most copies. Second, source priority: when two listings are the same job, the aggregator keeps the one from the highest-quality source and drops the rest. Stable provider IDs make this deterministic — the same input always resolves to the same surviving listing.
How does search stay fast at millions of listings?
The normalized jobs go into a search index — an inverted index over titles, descriptions, and skills, with faceted filters for location, salary band, remote vs on-site, and employment type. The expensive work (parsing, matching, ranking signals) happens at import time, so the hot path — a user typing a query — is a read-only lookup that returns in milliseconds.
How do listings stay fresh?
A job board's trust dies the day someone applies to a role that was filled three weeks ago. Freshness is a pipeline discipline:
- Re-check on schedule. Every source is re-fetched on its cadence, and listings carry expiry logic.
- Close carefully. A job missing from a source's latest fetch is marked closed — but only if that fetch succeeded. A timed-out request must never look like a mass closure, or one bad night deletes thousands of live jobs.
- Baseline first. The very first import is a silent baseline, so "new jobs" alerts don't start with a flood of thousands.
How are jobs ranked?
With duplicates gone and the index fresh, ranking decides what surfaces: title and skill relevance first, then freshness, source quality, and — on mature platforms — engagement signals like click-through and application rates.
Frequently asked questions
How do job aggregators get their listings?
From ATS APIs, bulk XML feeds, career-page crawling, and direct employer posting — usually all four at once.
Do job aggregators scrape websites?
Yes, crawling career pages is one of the four sourcing channels, alongside APIs and feeds. Responsible aggregators rate-limit requests, respect access rules, and back off under load.
How do job aggregators make money?
Typically through sponsored placements, cost-per-click or cost-per-application on outbound apply links, and employer branding products.
Building a job platform?
We have built the ingestion and feed systems behind high-volume job platforms — scheduled imports of millions of listings, normalization at scale, and search that stays fast. If you are building or scaling a job portal, talk to our engineering team.